RAG in Production: When Retrieval Actually Helps
Retrieval-augmented generation without the hype: how RAG works, when to use it, and the chunking, embedding and vector-DB choices that actually matter in production.
AI & automation · 2 min read · Kriyvo journal
In this article
Introduction
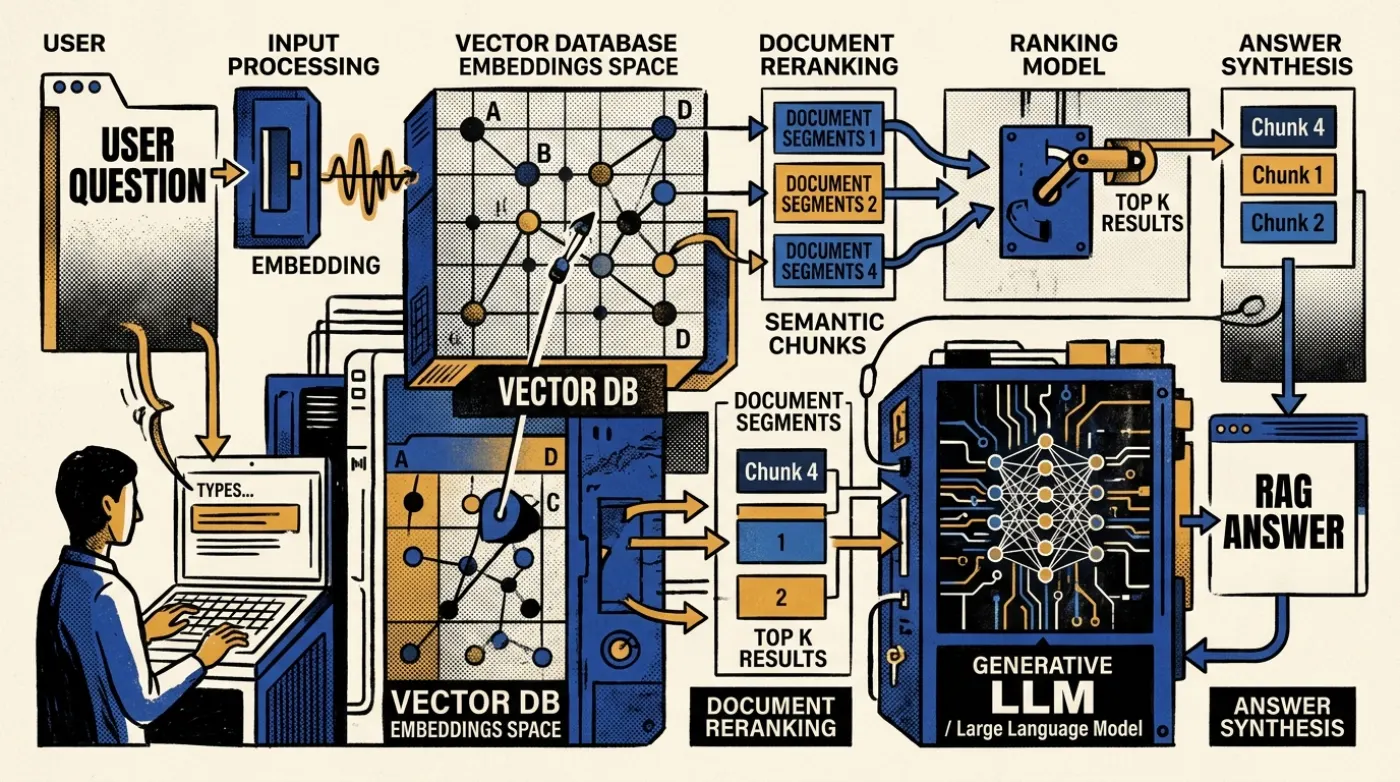
Deconstructing RAG: chunk size calibration, dense vector embeddings, and exact pgvector retrieval mechanics.
RAG — retrieval-augmented generation — is a practical pattern for making an LLM answer from retrieved source material instead of relying only on model memory. I use it when a system needs a larger or frequently changing knowledge base.
How RAG actually works
You split your documents into chunks, turn each chunk into an embedding vector, and store them in a vector database. At query time you embed the question, retrieve the most similar chunks, and hand them to the LLM as context. The model answers from real text, not memory.
The choices that matter
Chunk size and overlap affect whether retrieval finds the right passage. The embedding model influences recall, and the vector store shapes operational trade-offs such as filtering, scale and cost. Supabase pgvector is one option I use when Postgres fits the rest of the stack.
When not to use RAG
If your knowledge fits in a single prompt, skip the vector database. RAG earns its complexity only when the corpus is large or changes often. Engineering is knowing when not to add a moving part.
Need this built? LLM and AI agent development
Bounded AI applications and agents using Python, LangGraph, retrieval and controlled API integrations.
See the serviceWritten for the Kriyvo journal. Product claims reported by third-party sources are not independent Kriyvo AI benchmarks.