GPT Automation Architecture: A Production Breakdown
The reference architecture I use to put GPT-4 and Claude into production — prompt design, cost control, caching, and reliability patterns for AI automation.
AI & automation · 2 min read · Kriyvo journal
In this article
Introduction
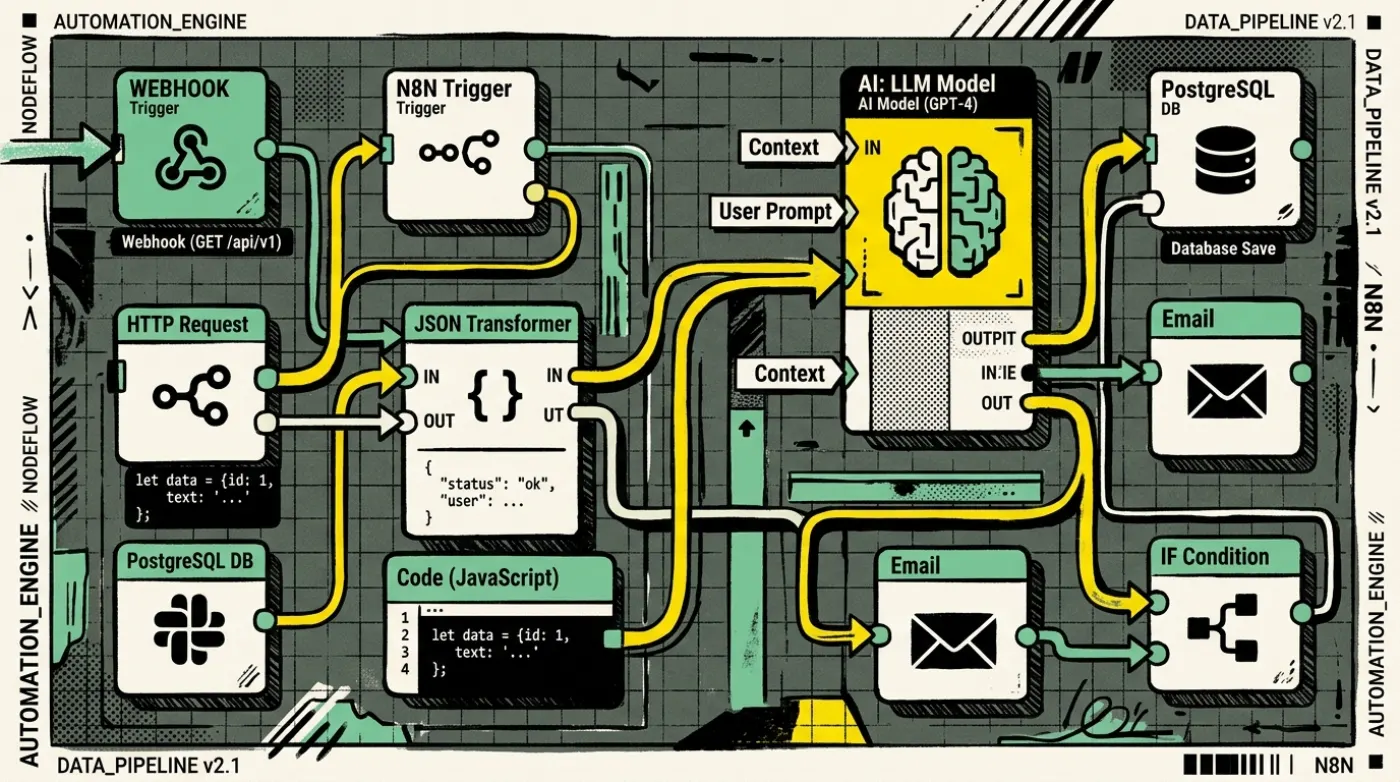
Reference production architecture for GPT-4: multi-tier prompt separation, semantic caching, and retry fallbacks.
Getting GPT-4 to answer a question is easy. Running it reliably and affordably at scale is the real engineering. Here is the reference architecture I use across my automation projects.
Layered prompt design
I split prompts into a stable system layer, a dynamic context layer, and a task layer. Only the context and task layers change per request, which keeps behaviour predictable and makes prompts easy to version and test.
Cost control and caching
Every LLM call adds cost and latency. Useful control patterns include caching deterministic sub-results, routing simpler tasks to cheaper models and reserving more capable models for harder reasoning.
Reliability patterns
Timeouts, retries with backoff, structured output validation, and a fallback path for every LLM node. If the model returns malformed JSON, validate it and use a defined repair, retry or fallback path. The Gignaati deployment-time result is a separate setup-automation metric, not a benchmark of LLM output handling.
Need this built? LLM and AI agent development
Bounded AI applications and agents using Python, LangGraph, retrieval and controlled API integrations.
See the serviceWritten for the Kriyvo journal. Product claims reported by third-party sources are not independent Kriyvo AI benchmarks.