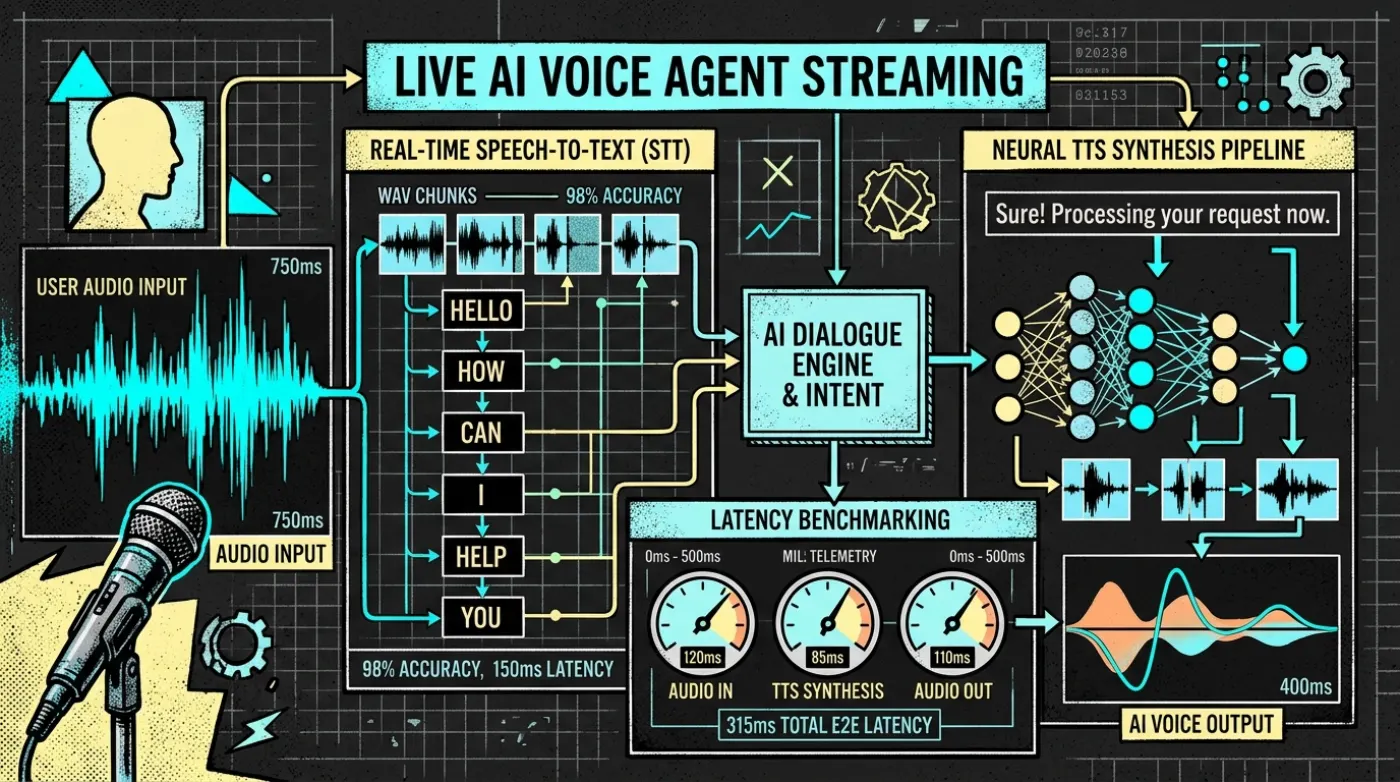
How to Benchmark AI Voice-Agent Latency
Set clear timer boundaries, test repeated voice turns, and report latency distributions instead of relying on a single best-case number.
Voice AI · 2 min read · Kriyvo journal
In this article
Introduction
Voice agent telemetry: round-trip audio latency, buffer constraints & streaming benchmarks
Low latency is difficult to evaluate when the timer is not defined. A voice system can measure time to the first model event, first audio chunk, first audible playback, or completion of the entire response. Those are different metrics and answer different questions.
A reproducible benchmark needs that context before the number can be compared or independently checked.
Choose the metric before testing
For conversational responsiveness, teams may measure the interval from the end of a user turn to the first audible response. They may separately track time to the first returned audio chunk and time until the complete response finishes. Document whether turn detection, buffering, network transport, and playback are inside each measurement window.
Control and describe test conditions
Record the client device, audio input, network conditions, geographic region, model or service configuration, and whether the connection was already open. Run repeatable scripted turns and representative natural speech. Do not mix cold connection setup with warm streaming turns without labeling the difference.
Repeat each scenario enough times to show variability. Report the sample count and a distribution such as median and p95 rather than the single fastest run. Preserve timestamps or traces that allow the team to reproduce the calculation.
Separate component timing and quality
Measure capture and buffering, network round trips, time to first model output, and playback startup separately when instrumentation supports it. This can distinguish model delay from client-side audio delay. Avoid presenting estimated component timings as a direct end-to-end measurement.
Latency is not the only acceptance measure. Check interruption behavior, intelligibility, unstable connections, errors, and dropped turns. A fast but incomplete response may not be useful.
A credible result states its start and end events, test conditions, sample size, and distribution. The documented voice-agent project provides context for its reported result.
Need this built? LLM and AI agent development
Bounded AI applications and agents using Python, LangGraph, retrieval and controlled API integrations.
See the serviceWritten for the Kriyvo journal. Product claims reported by third-party sources are not independent Kriyvo AI benchmarks.