How to Evaluate Feedback Classification Before Automating Routing
Build a reviewed test set and measure classification and routing separately before automating customer-feedback workflows.
Workflow design · 2 min read · Kriyvo journal
In this article
Introduction
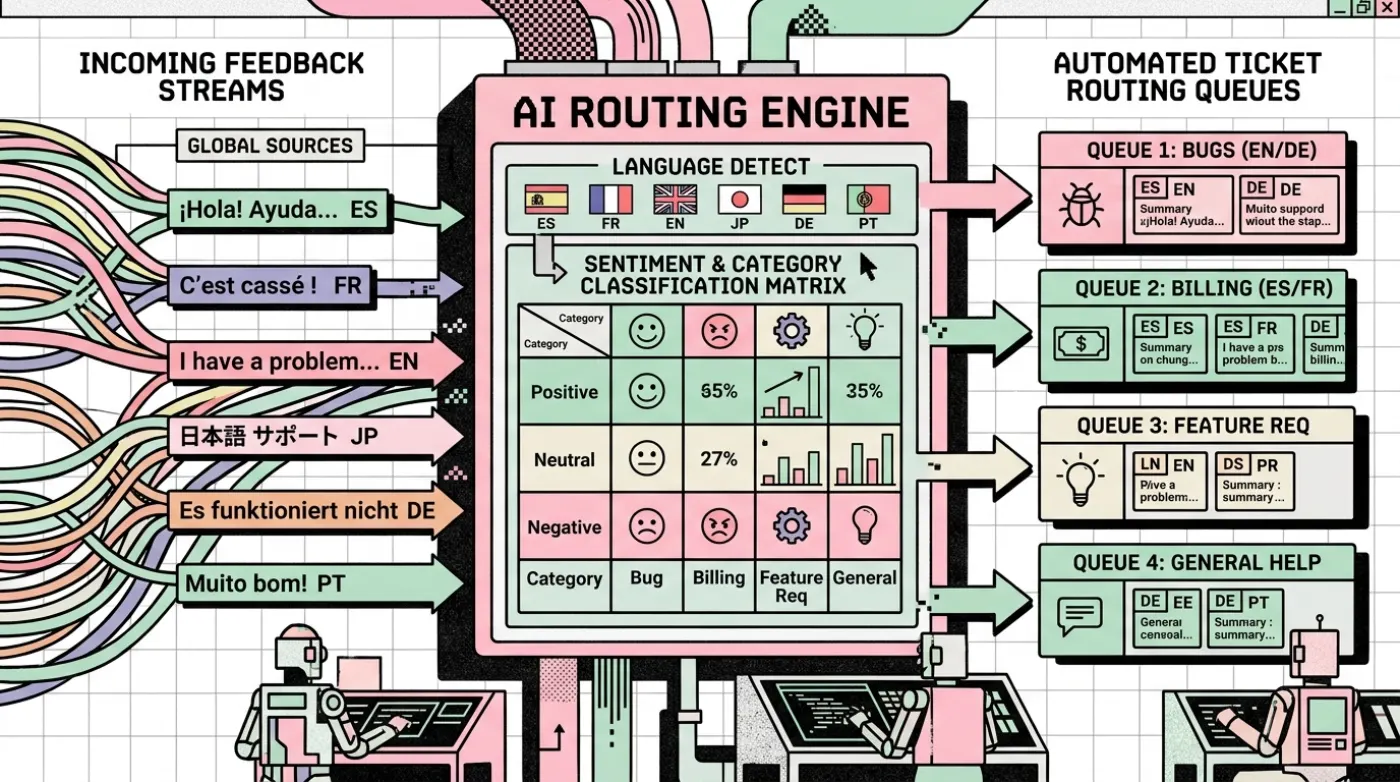
Classification evaluation matrix: sentiment categories, accuracy scoring & false positive triage
A model can return a confident-looking category without being right. Before feedback classification drives ticket routing, evaluate it against examples reviewed by people who understand the process. This helps identify weak categories and decide where human review is necessary.
Correctly identifying sentiment does not prove that a message reached the right team, and successful routing does not prove that the underlying interpretation was accurate. Measure those outcomes separately.
Build a representative evaluation set
Include the real mix of messages: short comments, mixed-language text, spelling variations, multiple issues in one message, and cases that do not fit a category. Remove or mask personal details before using samples in a test environment, following the organization's data-handling requirements.
Have reviewers apply a written category guide. Resolve disagreements about labels before treating them as ground truth. Record the intended destination separately from text classification so each step can be assessed independently.
Measure more than overall accuracy
Overall accuracy can hide poor performance on less common but important categories. Review a confusion matrix, per-category precision and recall, the rate of cases marked uncertain, and the share that needs correction. Inspect examples where a wrong category would change the team's response.
For the workflow, also track whether the destination was appropriate, required context was retained, and notifications reached the expected owner. Keep these operational measures separate from model metrics.
Set a fallback and re-test after changes
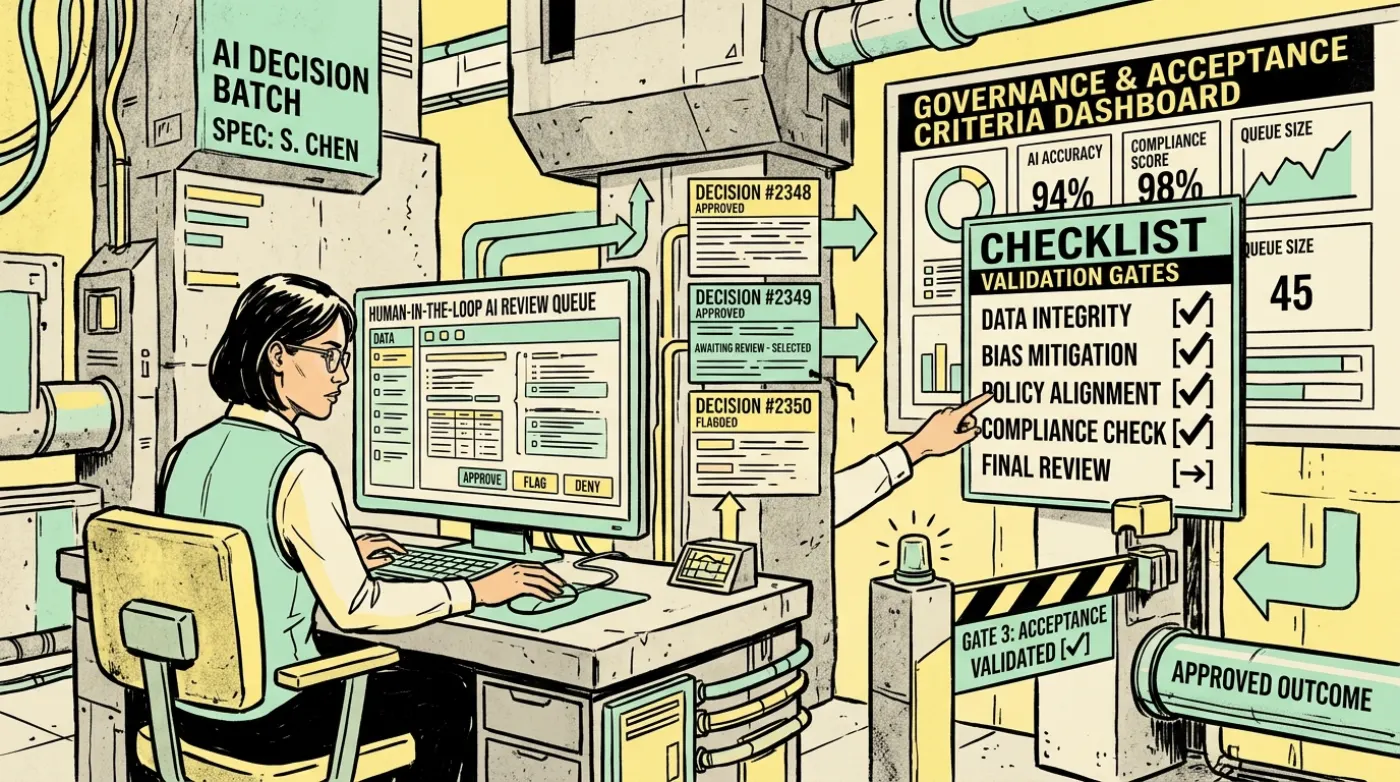
Choose a confidence or policy threshold only after examining representative results; a model's raw confidence is not automatically calibrated. Define a safe fallback for unsupported languages, ambiguous messages, missing context, or categories with too little evaluation data. A human queue is a valid outcome, not a system failure.
Keep a fixed regression set and periodically add reviewed examples under suitable privacy controls. Compare new results with the prior version before changing workflow behavior.
Need this built? n8n workflow automation
Maintainable n8n workflows for API and CRM integrations, AI-powered steps, lead processing, logging and failure handling.
See the serviceWritten for the Kriyvo journal. Product claims reported by third-party sources are not independent Kriyvo AI benchmarks.